From the Paralleliq team.
Deep dives into architecture, performance tuning, and operational excellence.
Model FLOPs Utilization: What Your GPUs Are Really Doing
GPU utilization tells you a GPU was busy. Model FLOPs Utilization (MFU) tells you how much of its compute went into the model. Here is what MFU is, what drags it down in training and in inference, and which of those causes can be fixed from the cluster.
GPU waste
Where capacity goes unused, how to see it, and what to change.
From GPU Waste Finding to Production Change: What Actually Happens in Between
Every GPU optimization tool will tell you what's wrong. Almost none of them tell you what happens next, between the moment an engineer agrees with a recommendation and the moment the fleet actually changes.
10 GPU Fleet Findings, and Who Each One Matters To
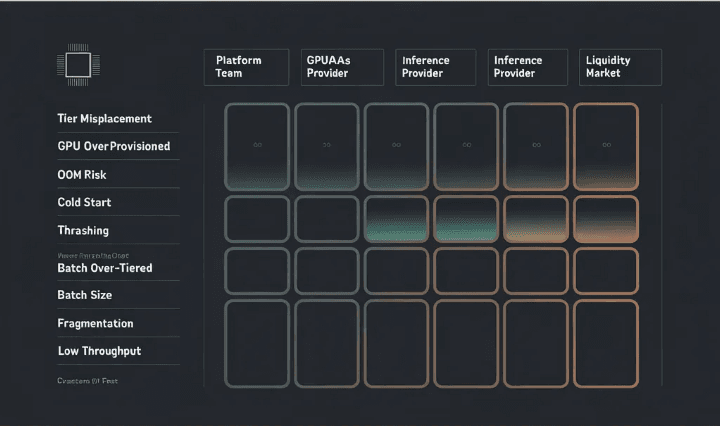
Not every GPU fleet problem looks the same from every seat. Here are the ten failure modes Paralleliq detects, what each one means, and why platform teams, GPUaaS providers, inference providers, and liquidity markets each care about different ones.
Your Online Inference Has an On-Call Engineer. Your Batch Jobs Run at 2am Alone.
Every AI team knows what their chatbot is doing right now. Nobody knows what their batch jobs cost. That's the gap, and it's where a surprising amount of GPU budget quietly disappears.
The GPU Shortage That Isn't
I asked a GPU cloud provider what their biggest pain point was. They said they're running out of GPUs. Here's why I think the real problem is somewhere else entirely.
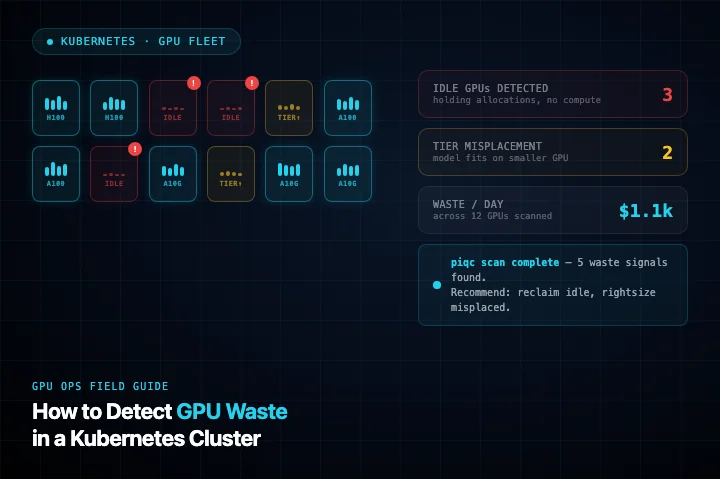
How to Detect GPU Waste in a Kubernetes Cluster
GPU waste in Kubernetes is largely invisible to standard monitoring. Here is what to look for, which metrics actually surface it, and how to go from suspicion to a concrete dollar figure.
Paralleliq vs. Cast.ai: Two Different Answers to GPU Waste
Cast.ai's own 2026 report found average GPU utilization of 5% across 23,000 Kubernetes clusters. Both Paralleliq and Cast.ai are trying to fix this, but from different angles, at different layers, with different trade-offs.
How to Detect GPU Underutilization in a Kubernetes Inference Cluster
GPU utilization percentage is the most-watched metric in AI infrastructure, and the most misleading. Here's what to measure instead, and how to instrument your Kubernetes inference cluster to catch waste before it compounds.
GPU Right-Sizing: Matching Tier to Workload
Running a 7B model on an H100 is as wasteful as running a 70B model on an A10G. Right-sizing GPU tiers is one of the highest-leverage cost optimizations in inference, and most teams get it wrong.
GPU Idle Time Explained: From Lost Cycles to Lost Momentum
Idle GPUs don't just waste compute; they waste runway, talent, and momentum. The real cost of GPU stalls is paid in stalled experiments and burnt-out engineers.
GPU economics
What a token, a GPU hour and a fleet really cost, and the decisions that move it.
The Router Solved Your Token Bill. Your GPU Fleet Didn't Get the Memo.
Enterprises are routing simple queries to cheap models and hard ones to heavy reasoning models to cut token costs. Nobody budgeted for what that does to the GPU fleet underneath, until the KV cache runs out at 2pm on a Tuesday.
How Token Compression Changes Your GPU Sizing Math
Token compression reduces what you pay per API call. Most teams stop there. The infrastructure math changes too: shorter contexts mean smaller KV cache requirements, which means a different GPU tier, more concurrency, and a lower GPU bill. Here is how to recalculate.
Selling GPUs Is No Longer Enough: Why GPU Clouds Are Becoming Optimization Platforms
CoreWeave, Lambda, Crusoe, and RunPod all sell the same H100s at roughly the same price. The GPU clouds that survive the coming commoditization wave will be the ones that help enterprise customers run workloads well, not just the ones that have the most hardware.
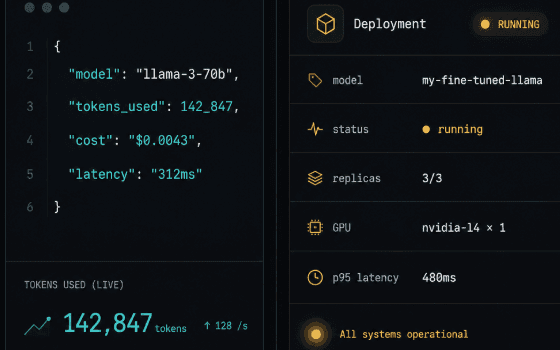
The Two Business Models Running AI Inference, and Why They Have Completely Different GPU Problems
Fireworks, Together, and Groq sell tokens. Baseten and Modal sell deployments. The same GPU waste looks completely different from each seat, and fixing it requires a completely different pitch.
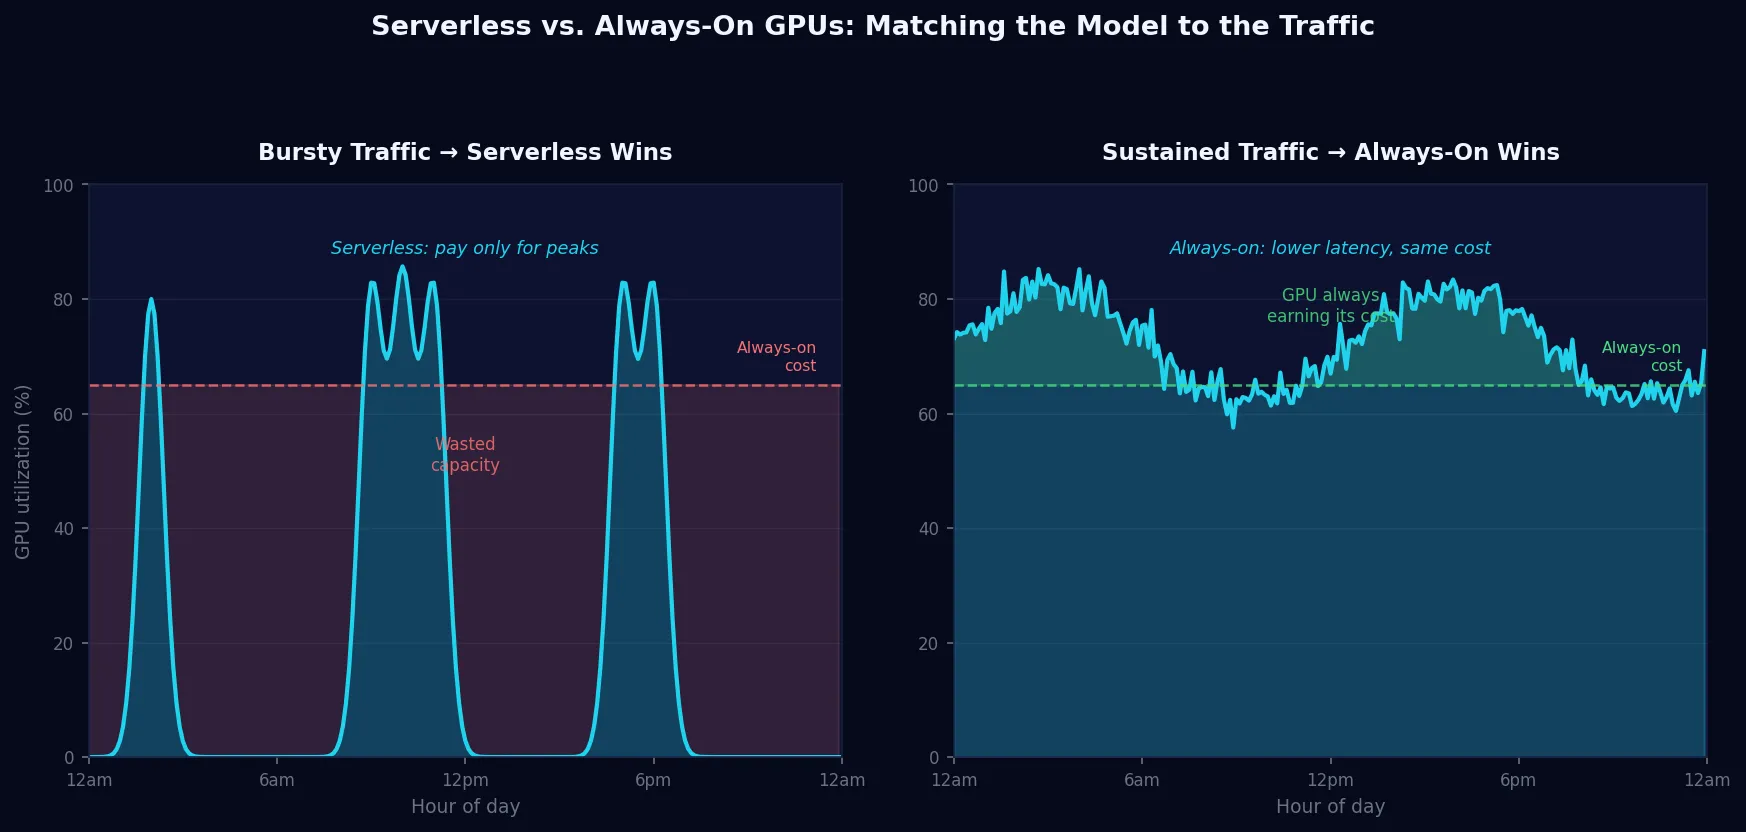
Serverless vs. Always-On GPUs: How to Know Which Your Model Actually Needs
Most teams choose between serverless and always-on GPUs by gut feel. Here's how to make the decision with data, and why getting it wrong costs more than you think.
Build vs. Buy: The GPU Optimization Layer Decision
Every team running GPU inference at scale eventually faces the same question: build an optimization layer internally, or buy one. The build path is deceptively expensive. Here's an honest breakdown.
How to Reduce LLM Inference Costs Without Sacrificing SLA
GPU costs for LLM inference are significant and often poorly optimized. These are the highest-leverage levers, ranked by impact and implementation effort, for reducing spend without degrading latency or throughput.
The #1 Silent Killer of GPUaaS Businesses
It's not hardware. It's idle GPUs. The economics of dedicated-only models break at scale, and better utilization is what fixes it.
The Financial Fault Line Beneath GPU Clouds
NeoClouds are caught between long-term GPU financing and short-term startup demand: the same structural mismatch that built the aircraft leasing industry.
Bare-Metal GPU Stacks: The Hidden Alternative to Hyperscalers
AI workloads continue expanding rapidly, driving up infrastructure costs. Bare-metal GPU providers deliver comparable hardware at reduced prices, but the savings come with operational responsibility.
Hyperscaler Credits: Friend, Trap… or Both?
When infrastructure feels 'free,' efficiency takes a back seat. Hyperscaler credits can be both a growth accelerator and a hidden liability, depending on how strategically they're deployed.
Extending the Runway: Surviving the GPU Cost Crunch After Cloud Credits
When credits expire, costs spike dramatically. Five strategic levers help startups protect their timeline while maintaining iteration speed.
Cluster efficiency
Running inference clusters well: configuration, memory, autoscaling and observability.
Beyond Prometheus: What Observability Actually Means for Model Inference
Prometheus is where most teams start monitoring GPU fleets, and it's nowhere near where the story ends. Here's the rest of the observability stack model inference actually needs.
Why We Built Paralleliq Like a Kubernetes Operator, Not a Scheduler
Most infrastructure tools work the same way: scan on a timer, compare against a threshold, raise an alert. That model breaks down the moment you actually want a system to act on what it finds. Here's the pattern we borrowed instead, and the one place we deliberately broke from it.
OpenInfer's Inference OS: What It Solves, and Where Paralleliq Starts
OpenInfer pitches itself as the first inference OS: dynamic, SLA-aware scheduling across a shared GPU fleet, the same idea that made cloud computing work for CPUs two decades ago. It's a real, well-built answer to a real problem. Here's what it actually does, and why it doesn't make a continuously audited fleet governance layer unnecessary.
Run:ai, AIBrix, and Determined AI: Where Each One Stops and Paralleliq Starts
Run:ai schedules GPUs. AIBrix optimizes vLLM serving within a cluster. Determined AI orchestrates training. All three get raised in the same breath as Paralleliq. Here's what each one actually does, and where the boundary actually is.
The Next Layer of Inference Efficiency: Cross-Instance KV Cache and Multi-Stage Serving
Two developments in the vLLM ecosystem, LMCache's cross-instance KV cache sharing and vLLM-Omni's multi-stage serving, point at where inference efficiency problems are heading next, and why a one-time configuration decision won't keep up.
15 Foundation Models, 15 Different vLLM Configs
The open-weight model zoo now has 15+ production-grade options. Each one has a different architecture, memory profile, and vLLM configuration requirement. That's not a model selection problem. It's an ops problem.
Why MoE Models Break Your vLLM Configuration Rules
The configuration rules that work for dense models fall apart with Mixture of Experts. A DeepSeek-scale MoE model needs the memory of a 671B model but the compute of a 37B one, and most teams configure it wrong.
How to Configure vLLM for Production
vLLM configuration is normally done through trial and error. Wrong max_num_seqs, misconfigured KV cache, or a bad speculative decoding decision can silently destroy throughput and latency. Here's how to get it right before you touch a cluster.
The One Sequence That's Killing Your LLM Inference Performance
When LLM inference slows down, the instinct is to look at infrastructure. But sometimes the culprit is a single request: one sequence quietly sitting in your batch, degrading latency and burning GPU budget for everyone else.
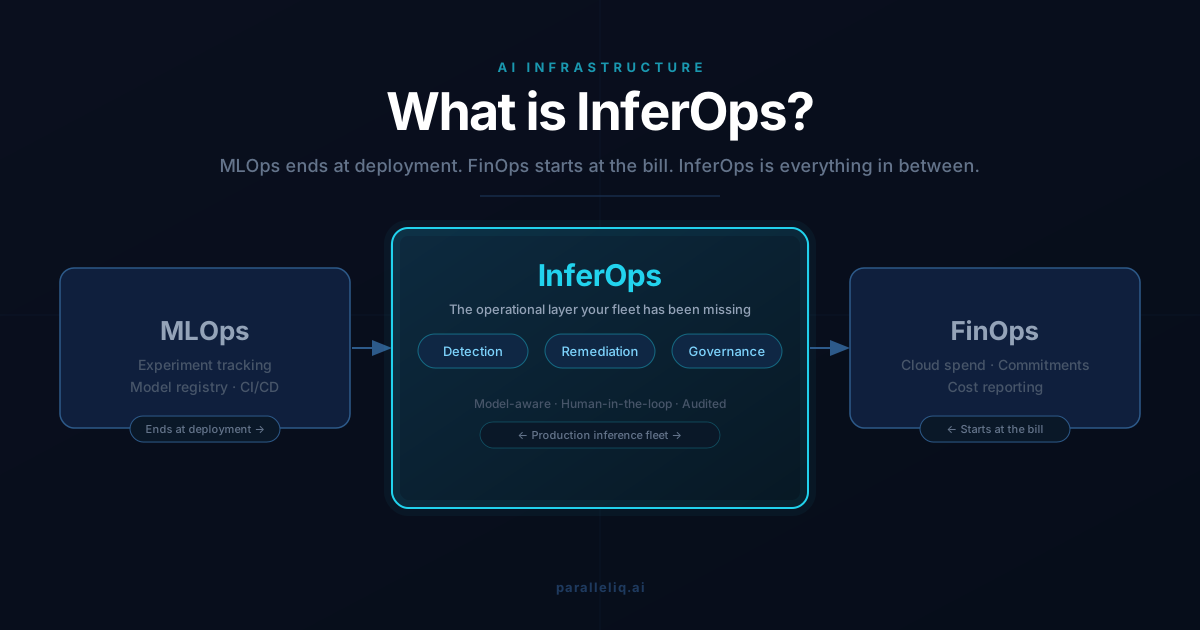
InferOps: The Category Nobody Named Yet
MLOps ends when the model is deployed. FinOps starts when the bill arrives. The operational gap in between, keeping inference fleets healthy, efficient, and production-ready, is InferOps. And most teams are doing it manually.
MIG Partitioning Is a Step Forward. Here's the Layer It Still Doesn't Solve.
Multi-Instance GPU partitioning lets you stop renting full cards for workloads that only need a slice. But who decides which model goes on which slice, and how do you manage that decision across a fleet?
The LLM Inference Autoscaling Stack: What Each Layer Solves, and the Gap None of Them Close
KEDA, Thoras.ai, llm-d, NVIDIA Dynamo, KServe, Run:ai. Each is real, each is useful. Here's what each layer of the inference autoscaling stack actually covers, and what the entire stack leaves unaddressed.
Why GPU Fleet Management Needs a Tenant Model
Single-cluster GPU tools break the moment you have multiple customers, multiple clusters, or multiple regions. Here's the organizational model that makes fleet-level control actually work.
What is a Model-Aware Optimization Layer?
As GPU fleets scale across clusters and regions, traditional infrastructure tooling breaks down. A model-aware optimization layer is what comes next, and why the distinction matters.
vLLM OOM Errors: Root Cause Diagnosis Guide
Out of memory errors in LLM inference are rarely random. They follow predictable patterns: KV cache overflow, batch size misconfiguration, memory fragmentation. Here's how to diagnose which one you're dealing with.
KV Cache Pressure: Symptoms, Causes, and Fixes
KV cache pressure is the hidden performance killer in LLM inference. When the cache fills up, throughput collapses and latency spikes, often without a clear error message. Here's how to detect and fix it.
CPU vs GPU Bottlenecks in Agentic AI Workloads
Agentic AI doesn't just run inference; it reasons, calls tools, manages memory, and orchestrates multi-step workflows. That changes the bottleneck. Here's how to tell whether your constraint is CPU or GPU.
GPU Fleet Observability: What to Monitor and Why
A single GPU dashboard is not fleet observability. At scale, the metrics that matter are aggregated, correlated, and surfaced as actionable signals, not raw telemetry. Here's what to build.
Serverless GPU Cold Start Latency: Causes and Solutions
Serverless GPU inference promises zero idle cost. The hidden trade-off is cold start latency, which for large LLMs can range from 30 seconds to several minutes. Here's what causes it and how to manage it.
Audit Trails for AI Infrastructure Changes
Who changed the GPU tier? Who approved the model rollout? Who scaled down the cluster before the incident? Without an audit trail, these questions take hours to answer. Here's how to build one.
Multi-Cluster GPU Visibility Across Providers
Most AI teams operate GPU infrastructure across multiple clusters, clouds, and providers. Getting a unified view of fleet health, cost, and utilization across all of them is one of the hardest operational problems at scale.
Beyond GPU Utilization: Why Compute Efficiency Is the New Metric That Matters
As agentic AI workloads blur the boundary between CPU and GPU work, measuring GPU utilization alone is no longer enough. Compute efficiency is the new metric that matters.
The Missing Layer in AI: Fleet Optimization as Competitive Advantage
The industry has over-invested in the data plane. The next frontier is not how fast you run models but how efficiently your fleet operates at scale. That's the optimization layer.
The Inference Stack: Routing and Serving Layers for LLMs in Production
A field guide to vLLM, TGI, Triton, TensorRT-LLM, SGLang, and Ollama, and the routing layers (L4, L7, inference-aware) that turn them into a production stack.
Why LLM Inference Deployment is Still a Guessing Game
Training a model feels like progress; deploying it often feels like panic. Engineers pick GPUs, batch sizes, and runtimes blind; inference deployment shouldn't be guesswork.
Too Hot, Too Cold: Finding the Goldilocks Zone in AI Serving
Every AI inference system operates between two extremes: maintaining numerous active workers delivers excellent response times but inflates GPU costs, while keeping few or no workers eliminates expenses but introduces cold-start delays.
Case studies
What changed, and by how much, on real teams' infrastructure.
Compliance-Aware AI Data Infrastructure for Healthcare
How an air-gapped configuration with policy-as-code and immutable audit trails took change-board review from weeks to hours for a HIPAA-constrained AI workload, a pattern that applies to any regulated environment, not just healthcare.
Cutting Drift Detection Time by 85%: Observability That Transforms MLOps
How a platform team replaced a tangle of per-model drift probes with one signal operators actually trusted, and why centralizing policy while distributing data was the fix, before Paralleliq existed.
Faster AI Model Releases with 40% Fewer Incidents
How a mid-market team went from quarterly model releases to weekly ones by modernizing serving infrastructure with KServe and Triton, and cut incidents 40% along the way, before Paralleliq existed.
Cutting AI Training Costs by 40%: No Trade-Offs in Performance
How a growth-stage AI team closed the gap between 90%+ reported utilization and a training bill that kept climbing anyway, before Paralleliq existed, using the same class of diagnosis it now automates.
The archive
38 earlier posts on AI strategy, model deployment and AI in specific industries.